NetsanetGeb commented on issue #714: Performance Comparison of HoodieDeltaStreamer and DataSourceAPI URL: https://github.com/apache/incubator-hudi/issues/714#issuecomment-510569606 **### Bench marking Hudi Upsert** I am trying to bench mark Hudi upsert operation and the latency of ingesting 6 GB of data is 38 minutes with the cluster i provided. How can i enhance this? For my specific use case, i used a spliced JSON data source with the schema having 20 columns. The settings i used for a cluster with (30 GB of RAM and 100 GB available disk) are: spark.driver.memory = 4096m spark.executor.memory = 6144m spark.executor.instances =3 spark.driver.cores =1 spark.executor.cores =1 hoodie.datasource.write.operation="upsert" hoodie.upsert.shuffle.parallellism="1500" You can see the details from the UI of the spark job provided below: 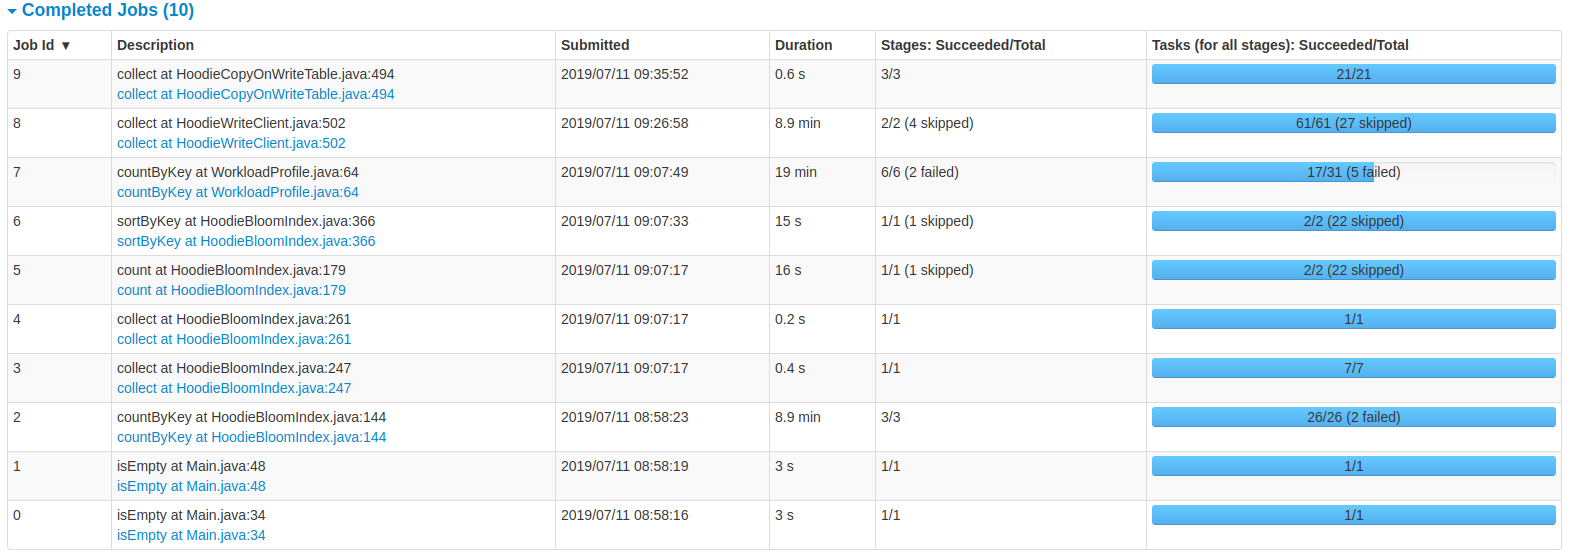 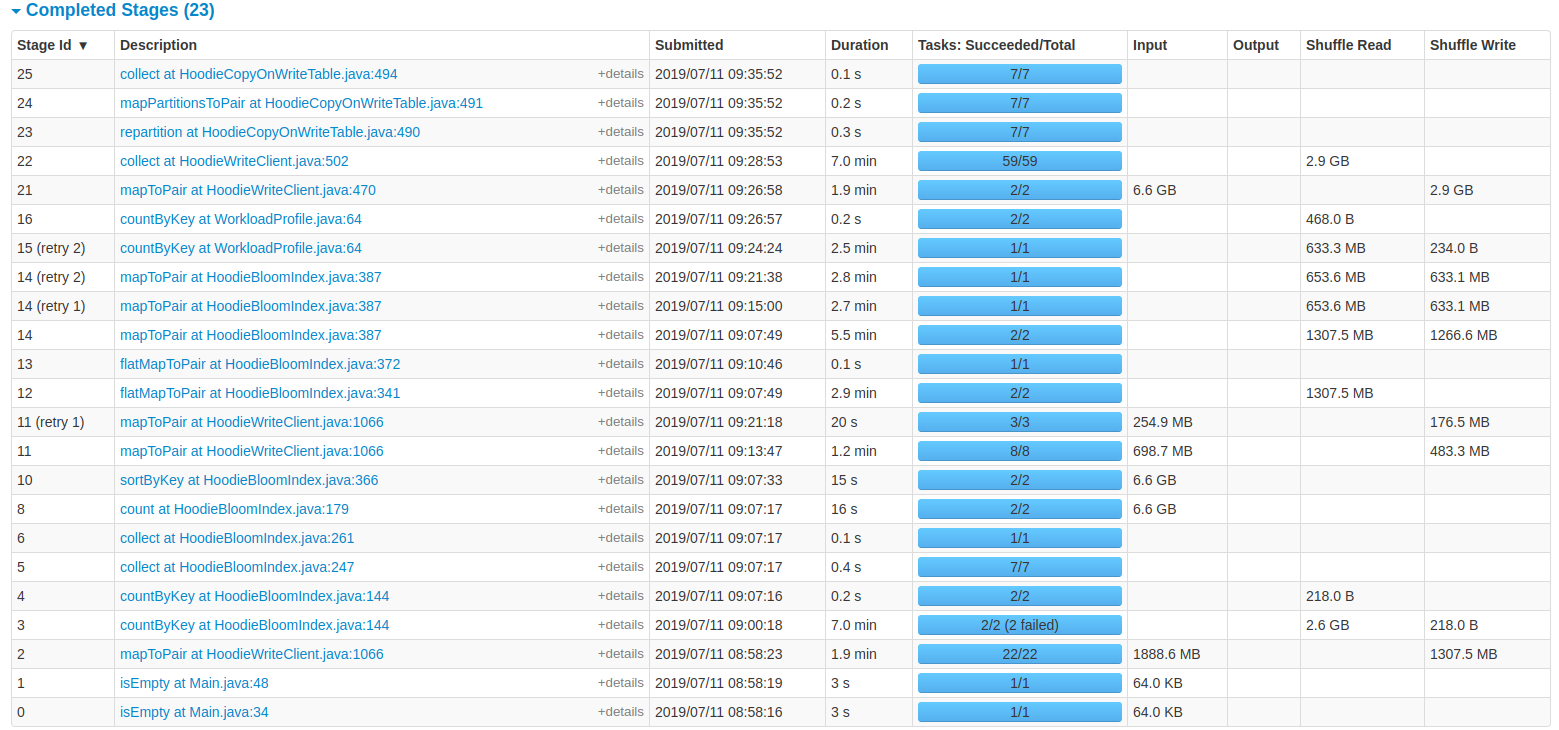
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
[email protected]


With regards,
Apache Git Services


