bitflicker64 opened a new issue, #3183:
URL: https://github.com/apache/hugegraph/issues/3183
### Bug Type (问题类型)
logic (逻辑设计问题)
### Before submit
- [x] I have confirmed and searched that there are no similar problems in
the historical issues and documents
### Environment (环境信息)
- Server Version: master (98477f0f), so this lands in 1.8.0
- Backend: hstore, 3 PD x 3 Store x 3 Server on Kubernetes (Helm chart from
#3132), PD image `hugegraph/pd` built from the same commit
- OS: kubeadm 1.34 cluster, 3 worker nodes, Ubuntu 24.04
- Data Size: n/a, the problem is in cluster membership, not data
### Expected & Actual behavior (期望与实际表现)
**Expected.** A PD that cannot take part in raft (no leader, or fewer than a
quorum of members reachable) should not report itself as ready. Anything that
gates on PD health, whether a Store waiting to register, `wait-storage.sh` on
the Server, or a Kubernetes readiness probe, should be held back until the PD
can actually serve.
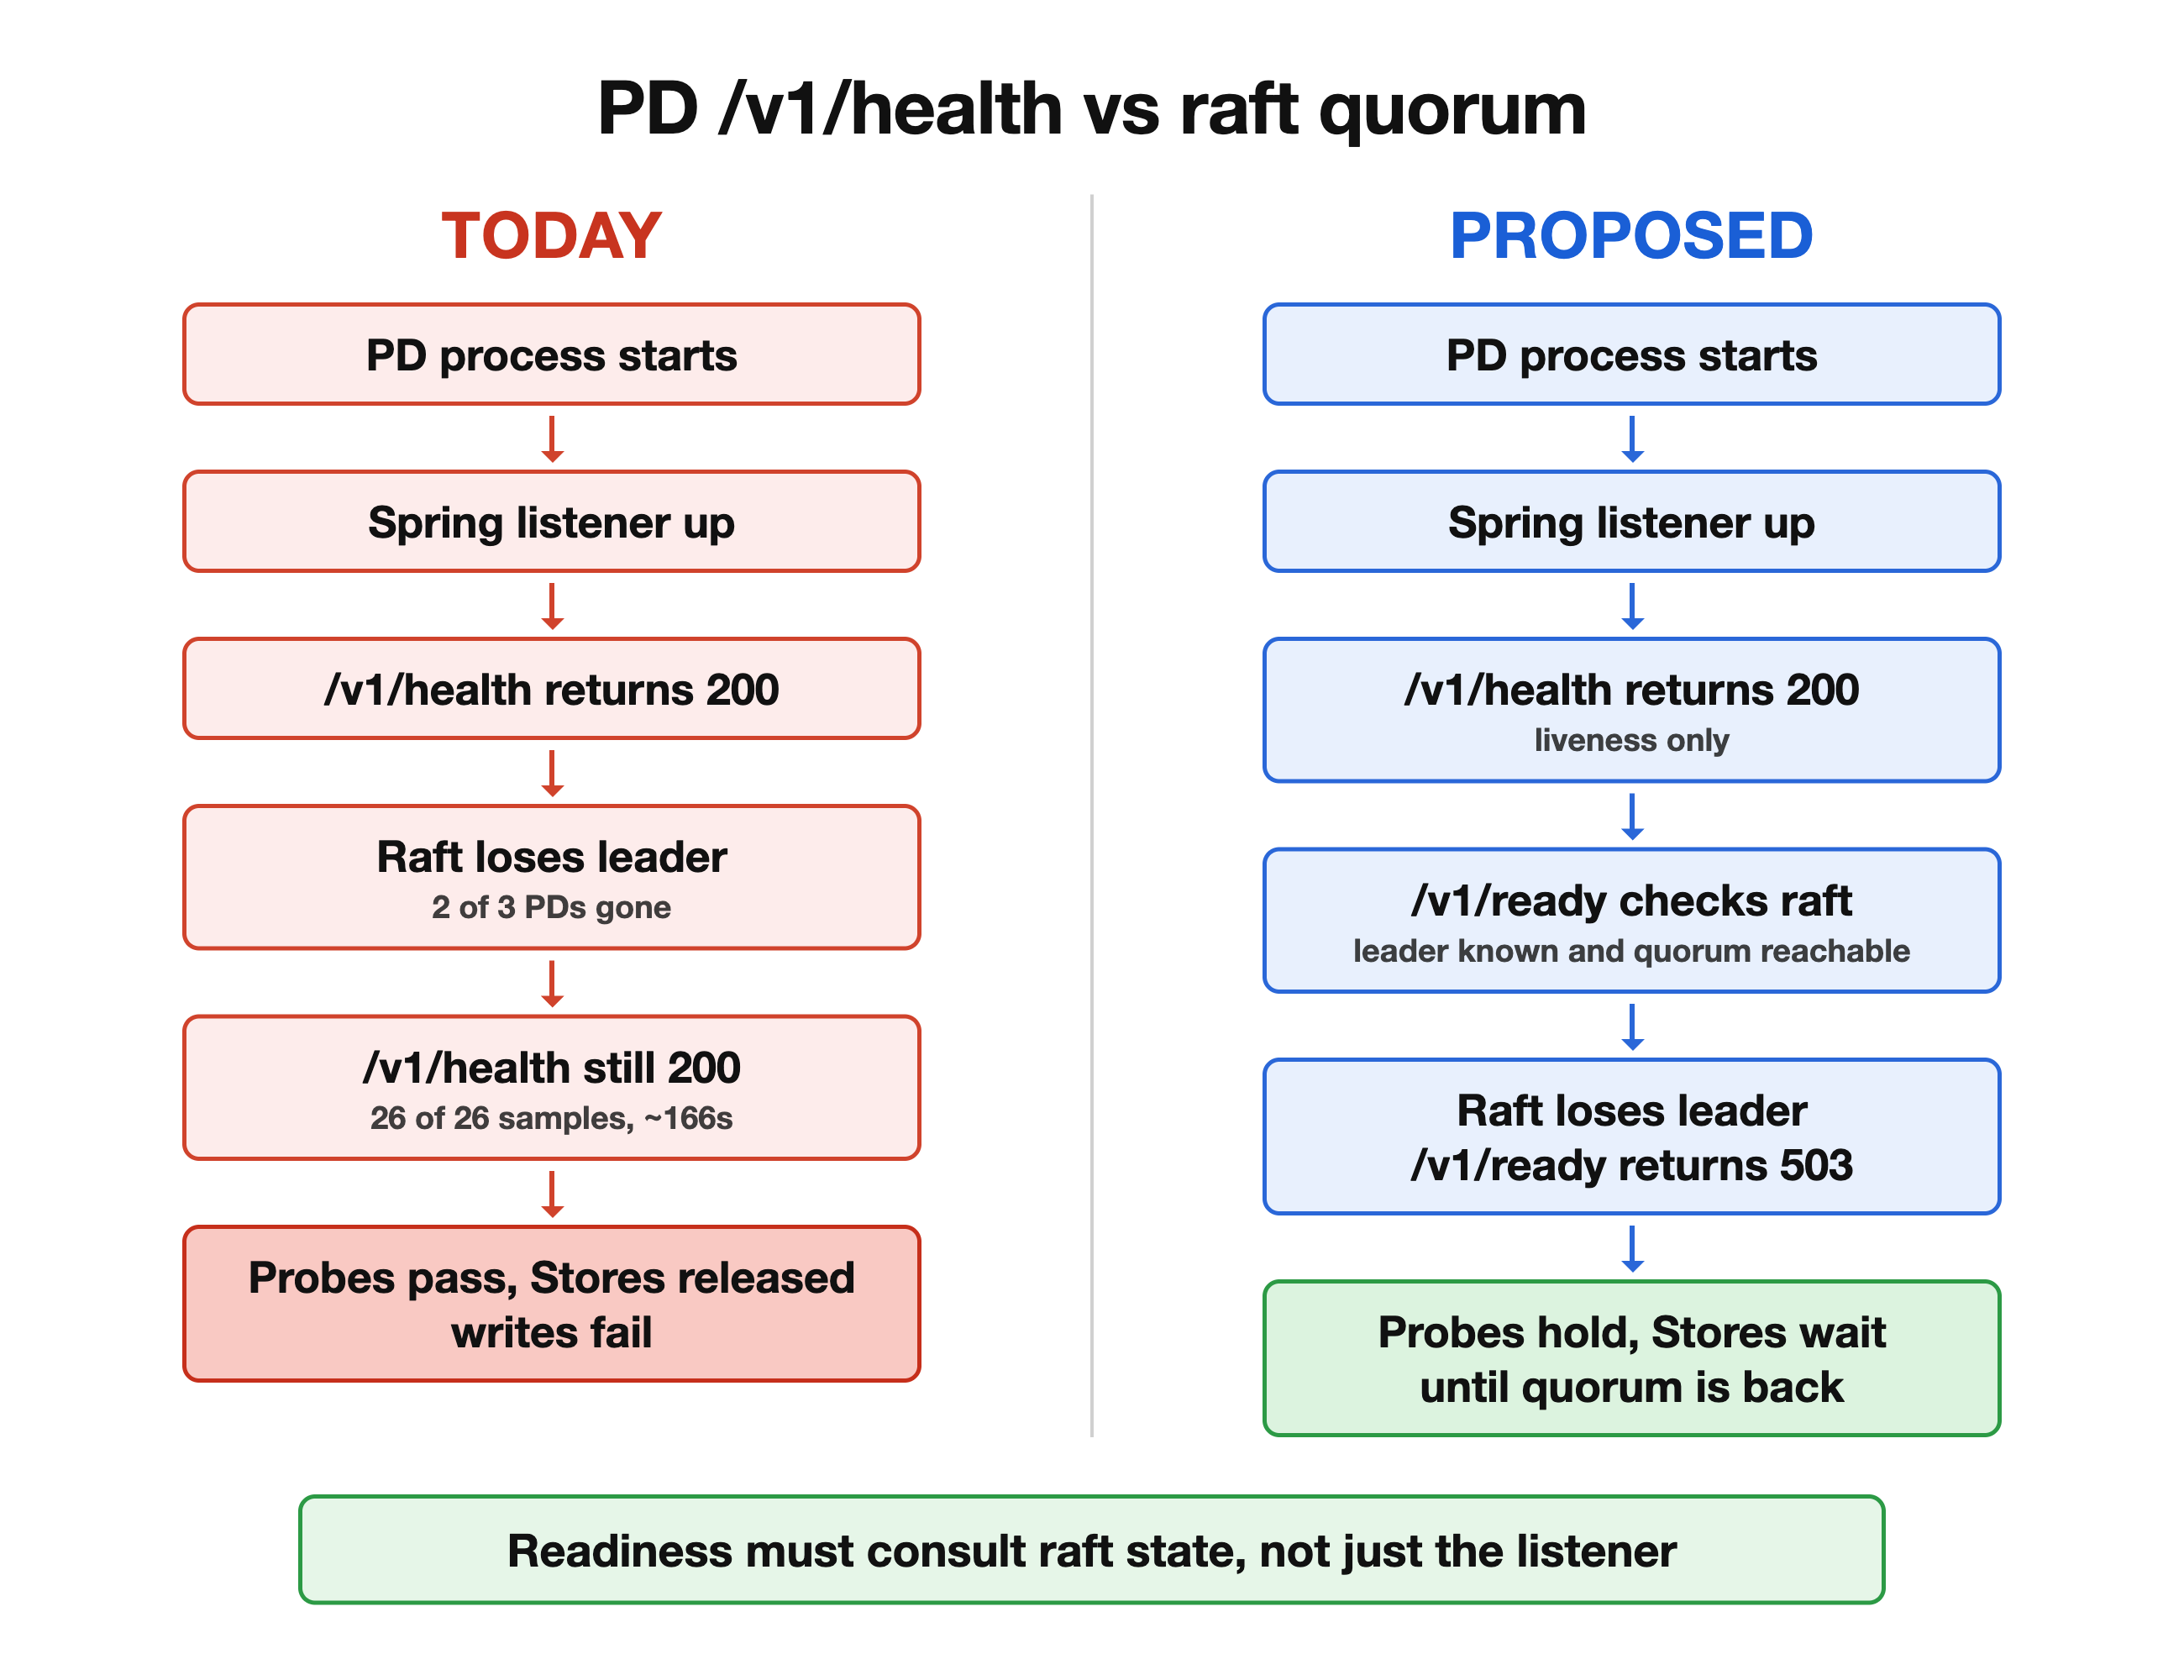
**Actual.** `/v1/health` answers 200 as soon as the Spring listener is up
and never consults the raft state. In
`hugegraph-pd/hg-pd-service/.../rest/StoreAPI.java`:
```java
@GetMapping(value = "/health", produces = MediaType.TEXT_PLAIN_VALUE)
public Serializable checkHealthy() {
return "";
}
```
Measured on a 3-PD cluster after deleting two of the three PD pods: the
survivor logged `Raft lost leader` within one second of the fault and then kept
answering `200` to `/v1/health` on every one of 26 samples over about 166
seconds, while calls that need a leader failed for roughly 50 seconds until the
replacements rejoined. Same process, same second, two different answers.
Everything that consumes `/v1/health` inherits the mismatch:
- `bin/wait-storage.sh` on the Server (after #3129 it retries every peer,
which fixed the fail-over, but a 200 from any peer still counts as "PD is up").
- The Store's wait for PD before it registers.
- In the Helm chart, the startup, readiness and liveness probes on both PD
and Store, and the Store init gate that waits for a quorum of PDs. That gate
can release Stores against a PD that has no leader.
I looked for something else to build a real gate on and did not find an
unauthenticated option:
- `/actuator/prometheus` exposes `hg_up`, `hg_stores`, `hg_terms` and
`hg_graphs`. There is no leader flag and no member count, and `hg_terms` read 0
on a live leader, so it cannot stand in for one.
- `/v1/members` does carry what is needed (`pdLeader` with `role` and
`state`, plus the member list) but it sits behind the REST auth interceptor. A
kubelet probe cannot send a credential and should not have to.
### Proposal
Any of these would close the gap, listed in order of how little they change:
1. Make `/v1/health` return a non-2xx status when the local node has no raft
leader or is not part of a quorum. This is the smallest change but it turns a
liveness signal into a readiness one, which may not be what every caller wants.
2. Keep `/v1/health` as pure liveness and add an unauthenticated `/v1/ready`
(or `/v1/health?ready=true`) that returns 200 only when the node has a leader
and is inside a quorum. The Helm chart and `wait-storage.sh` would switch to it.
3. Independently of 1 or 2, add a raft leader gauge (1 on the leader, 0
elsewhere) and a reachable-member count to the actuator metrics so operators
can alert on quorum loss.
Option 2 plus 3 seems like the right shape. Happy to send a PR for whichever
direction is preferred.
### Related
- #3123 and #3129 fixed `wait-storage.sh` sticking to one peer. This issue
is the remaining half: the signal it now polls on every peer does not mean what
the script needs it to mean.
- The Helm chart in #3132 documents this as a limitation and keeps all
probes on `/v1/health` until a quorum-aware endpoint exists.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: [email protected]
For queries about this service, please contact Infrastructure at:
[email protected]

