bitflicker64 opened a new pull request, #3234:
URL: https://github.com/apache/hugegraph/pull/3234
## Purpose of the PR - Fixes #3227 A Store whose data volume is lost comes back at the same raft address (on Kubernetes the StatefulSet always rebuilds the Pod under the same DNS name; on bare metal, any rebuild that reuses host:port) but registers with PD under a new store id. Retiring the old id per the documented procedure (`Tombstone`, then `patrolPartitions`) never repairs the groups: every group ends up naming a store id that no longer exists, the rebuilt Store holds no partitions, every group runs on two live replicas, and `/v1/stores`, the cluster state, Hubble and Pod readiness all read healthy. #3227 has the full measurement and a diagram of the loop. There were two faults, and both had to go: 1. **No data ever reaches the rebuilt Store.** `reallocShards` puts the new id Y into each group and fires ChangeShard. The group leader maps the ids to raft endpoints (`shards2Peers`), gets the same endpoint set it already has, so `changePeers` adds nothing. The rebuilt Store never gets a raft node for any group, and jraft only installs a snapshot into a node that exists. On the #3227 run the leaders logged `Replicator stateChanged hugegraph-store-2...:8510 OFFLINE` for that address 11,814 times on store-0 alone. 2. **The old id keeps coming back.** The leader's local `ShardGroup` still lists the old id X. Its partition heartbeat (`HeartbeatService.partitionHeartbeat`, every 5 s) sends that list, and `PartitionService.partitionHeartbeat` overwrites PD's corrected group with it. On the #3227 run PD rewrote group 1 with X three seconds after `reallocShards` wrote Y (`Raft 1 updateShardGroup ... store_id: 1190848017232829764` at 17:59:47, PD leader log). `onConfigurationCommitted` resolves endpoints through the same stale list, so any later leader change would do the same. 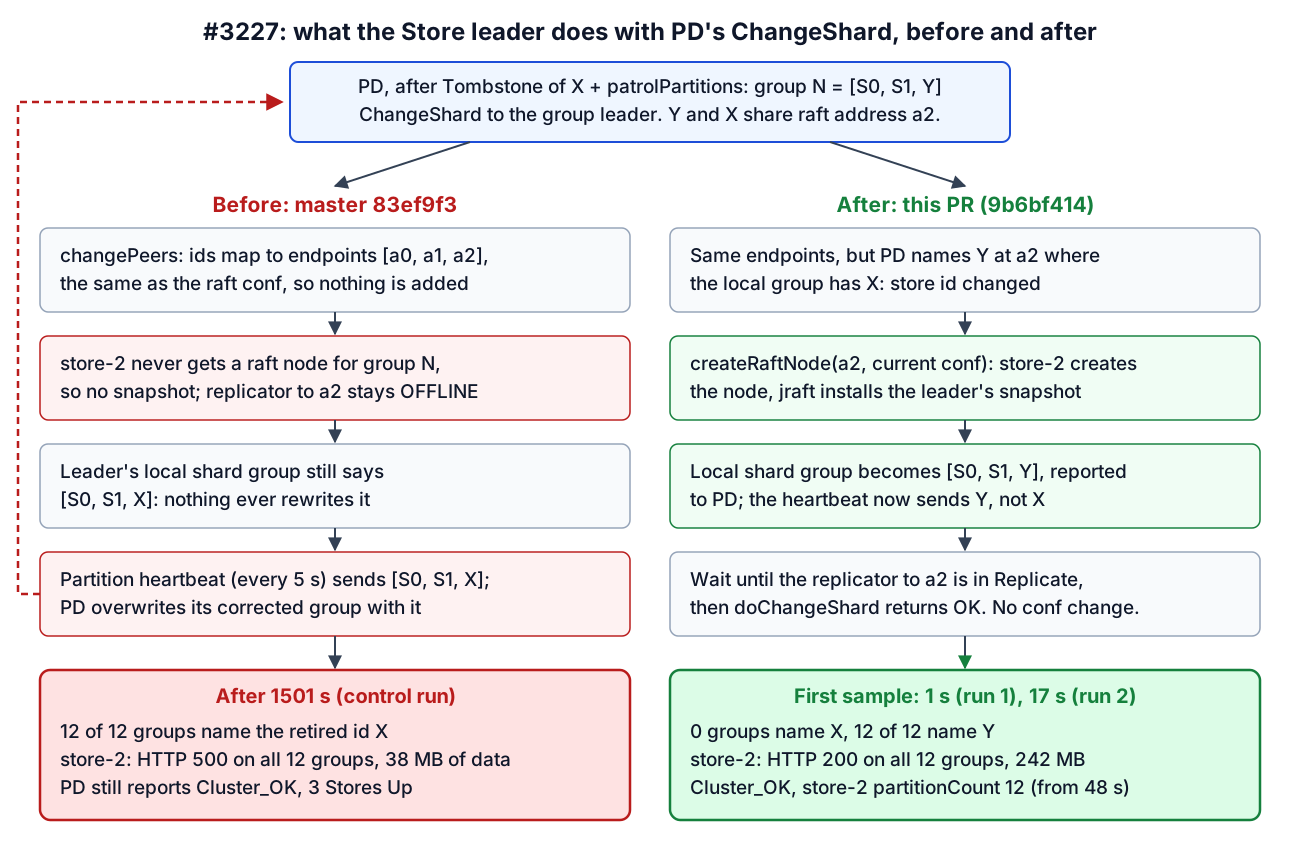 ## Main Changes All in `hg-store-core`, Store side only. No PD, proto or configuration change. - `PartitionEngine.doChangeShard`: after `changePeers`, call the new `syncShardIdentities`. When PD's shard list and the raft configuration have the same endpoints but PD names another store id at one of them (never the leader itself), the leader: 1. sends `createRaftNode` to that endpoint with the current configuration, so the rebuilt Store creates the raft node and jraft installs the leader's snapshot into it (the same RPC `changePeers` already uses for new learners); 2. takes PD's ids into its local shard group (roles from the live configuration), persists it and reports it to PD, which stops the heartbeat overwrite; 3. waits until the peer's replicator reaches `Replicate` (the existing wait loop, moved into `waitForReplicate` so both paths share it). A timeout returns `TASK_CONTINUE`, which the existing retry handles. No raft membership change happens: the endpoint is already a voter, and the rebuilt node joins that slot with an empty log. - `PartitionManager.getStoreByRaftEndpoint(ShardGroup, Metapb.ShardGroup, String)`: when the id the local group holds for an endpoint is no longer in PD's current group, use the id PD's group has at that endpoint. `onConfigurationCommitted` fetches PD's group once and resolves through it, so a leader change after the repair does not put the old id back. The two-argument overload is unchanged. - `StoreIdChangeTest` (in `CoreSuiteTest`): endpoint resolution when the local id is still valid, retired, or deleted from PD, and the endpoint-diff rule (finds a new id at an unchanged address, ignores real membership changes, never includes the leader itself). Not in this PR: PD retiring the old record by itself when a new id registers at its raft address. The documented `Tombstone` step is still needed to start the repair; with this change it now works. Readiness while a rebuilt Store catches up stays with #3229. ## Verifying these changes - [ ] Trivial rework / code cleanup without any test coverage. (No Need) - [ ] Already covered by existing tests, such as *(please modify tests here)*. - [x] Need tests and can be verified as follows: - Unit: `mvn test -pl hugegraph-store/hg-store-test -am -P store-core-test` runs 30 tests, 8 of them new, 0 failures (22 before). `store-raftcore-test` (9) and `pd-core-test` (104, 2 skipped) unchanged and green; `editorconfig:check` clean. JDK 11, run 2026-09-24. - End to end: the #3227 scenario (S2b) on kind, 3 PD + 3 Store + 3 Server + Hubble, NetworkPolicy on, 12 shard groups, about 9k vertices loaded plus a live writer. Delete store-2's PVC and Pod, wait for the new id to register, `Tombstone` the old id on the PD leader, `patrolPartitions`, wait up to 25 min. Same script, same chart, same host, only the Store/PD/Server images differ. Control: the `:latest` images #3227 was measured on (apache master `83ef9f3`, store `sha256:7bc0cbd81550`). Fix: images built from this branch (`9b6bf414`, revision label checked in the pod). | | Control (`83ef9f3`) | This PR (`9b6bf414`) | |---|---|---| | Groups naming the old id after Tombstone + patrol | 12 of 12, after 1501 s | 0 of 12, at the first sample: 1 s (run 1), 17 s (run 2) | | Groups naming the rebuilt Store | 0 | 12 | | Rebuilt Store `:8520/v1/partition/{id}` | 500 for all 12 | 200 for all 12, same key counts as the leader per table | | Rebuilt Store data dir | 38 MB (survivors 246 MB) | 242 MB (survivors 243, 244 MB) | | After `DELETE /v1/store/{old}` | 12 groups name the deleted id | 0 groups name it | | `/v1/stores` and cluster state | 3 `Up`; rebuilt Store `partitionCount` 0; `Cluster_OK` | 3 `Up`; rebuilt Store `partitionCount` 12; `Cluster_OK` (run 2, from 48 s on) | | Acknowledged writes lost | 0 of 3182 | 0 of 429 (run 1), 0 of 1492 (run 2) | Run 2 (same images, fresh cluster) adds a 5-minute health watch after convergence, a second `patrolPartitions`, and a restart of the rebuilt Store with its PVC kept. It converged 17 s after the Tombstone. From the 48 s sample on, every 30 s sample read `Cluster_OK`, the rebuilt Store `Up` with `partitionCount` 12, and all 12 groups `PState_Normal`. The second patrol changed nothing. The restarted Store was Ready in 151 s under the same id, with 0 container restarts, no `is illegal` exit in `loadPartitions`, and all 12 groups served. The Store-level `partitionCount` follows the Store heartbeat (30 s), so it lags the repair: run 1 sampled it 1 s after the Tombstone and saw `partitionCount` 0 and `Cluster_Warn` while the snapshots were still installing. Store leader log on the fixed run, per group (store-0 and store-1 between them cover all 12): ``` Raft 3 store id changed at raft address [hugegraph-store-2.hugegraph-store.hg.svc:8510], local {...=X}, pd {...=Y} Send to hugegraph-store-2.hugegraph-store.hg.svc:8510 CreateRaftNode rpc call ... Raft 3 shard group after store id change [... store_id: 239294855241425130 ...] Raft 3 doChangeShard result is Status[OK] ``` Evidence (scripts, run logs, per-Store partition views, PD and Store logs, write ledgers): [bitflicker64/hugegraph `logs/fix-3227`](https://github.com/bitflicker64/hugegraph/tree/logs/fix-3227) (`s2b-run.sh` is the harness, `README.md` lists the layout, one folder per run) ## Does this PR potentially affect the following parts? - [ ] Dependencies ([add/update license](https://hugegraph.apache.org/docs/contribution-guidelines/contribute/#321-check-licenses) info & [regenerate_known_dependencies.sh](../install-dist/scripts/dependency/regenerate_known_dependencies.sh)) - [ ] Modify configurations - [ ] The public API - [x] Other affects: Store raft membership handling on ChangeShard (`hg-store-core`) - [ ] Nope ## Documentation Status - [ ] `Doc - TODO`: required documentation is pending; complete it before merging. - [ ] `Doc - Done`: documentation is included here or linked below. - [x] `Doc - No Need`: no user-visible documentation is affected. Documentation files in this PR or paired hugegraph-doc PR: The Helm chart README (#3218) currently tells operators never to delete a Store volume. That warning changes once this merges; see the list below. ## After this merges For whoever picks this up next. Nothing here blocks the merge. 1. **Rerun the #3227 scenario on images built from merged master.** On a host with Docker, kind, helm and about 12 GB free memory (the runs above used 12 cores and 15 GB): - Check out apache/hugegraph `master` at or after the merge commit of this PR, then build the images with the revision label: `SHA=$(git rev-parse HEAD); IMAGE_TAG=m3227 SOURCE_REVISION=$SHA docker buildx bake -f docker/bake.hcl pd store server-hstore --set '*.platform=linux/amd64' --set "*.labels.org.opencontainers.image.revision=$SHA" --load`, and tag each as `hg3227/{pd,store,server}:master`. (Or use the Docker Hub `:latest` published after the merge, and record its digests and revision instead of building.) - Run `OBSERVE_S=300 WAIT_S=1500 bin/s2b-run.sh master` with the harness linked under Evidence. It expects the chart under `~/hg-3227/chart/helm/hugegraph`, and `harness/kind.yaml`, `writer.sh` and `verify-ledger.sh` from the evidence folder under `~/hg-lifecycle` (`kind.yaml` at the top, the two scripts in `scripts/`). It also needs the images `hg3227/hubble:control` and `hg3227/probe:1`, the latter built from `harness/probe.Dockerfile`. - Pass: `converged=1`; 0 groups naming the old id and 12 naming the new one; the rebuilt Store answers 200 on all 12 `:8520/v1/partition/{id}`; after the observation window `/v1/stores` shows the rebuilt Store `Up` with `partitionCount` 12 and the cluster `Cluster_OK`; the store-2 restart with its PVC comes back with 12 of 12 and no `is illegal` line; `missing=0` in the ledger. Attach the `s2b.log` and `health.log` to this PR as a comment. 2. **Update the Helm chart README** (hugegraph/hugegraph branch `feat/hstore-helm-chart-3132`, the head of apache PR #3218 and its mirror hugegraph/hugegraph#221, file `helm/hugegraph/README.md`). Two places say a Store volume must never be deleted: the paragraph starting "**Do not delete a Store's PersistentVolumeClaim on current images.**" under Disaster Recovery, and the first bullet of "## Limitations" ("A Store cannot be recovered in place after its volume is lost"). Replace them with the retirement procedure that now converges (find the old id at the replaced Pod's address, `POST /v1/store/{oldId}` with `{"storeState":"Tombstone"}` on the PD leader, `patrolPartitions`, verify every group lists only `Up` Stores and the replaced Store's `:8520/v1/partition/{id}` answers 200, then `DELETE /v1/store/{oldId}`). Keep a version caveat: images built before this PR's merge commit, including every published 1.7.x image and `:latest` before that merge, still cannot recover in place, an d the old warning applies to them word for word. Only make this change after step 1 passes, and cite the step 1 run in the commit message. 3. **Keep #3229 open.** This PR does not change when a Store reports `Up` or add a readiness signal. It does change what #3229 is about: before, a Store rebuilt with an empty volume never received data, so "Up but empty" lasted forever; now it receives a snapshot for every group after the old id is retired, and the remaining gap is the window between `Up` and caught-up (1 s on the 243 MB test data, longer on real data), plus the stale `Up` of a stopped Store. Post one short comment on #3229 saying this, linking this PR. 4. **Add the scenario to the testing skill as a permanent regression case** (repo bitflicker64/hugegraph-helm-testing): copy `s2b-run.sh` from the evidence into `scripts/lifecycle/`, add a row for it to `scripts/lifecycle/README.md`, and add a section to `references/test-suite.md` under Lifecycle with the procedure, the pass criteria from step 1, and the expected control result on images older than this merge (12 of 12 groups keep the old id, rebuilt Store 500 on every group, `Cluster_OK` throughout). Mark the old S2b finding in that file as fixed by this PR. 5. **Tell @imbajin it landed.** Once step 1 passes, one comment on this PR mentioning him, with the merge commit, the step 1 result in one line, and a link to the #3218 README change from step 2. -- This is an automated message from the Apache Git Service. To respond to the message, please log on to GitHub and use the URL above to go to the specific comment. To unsubscribe, e-mail: [email protected] For queries about this service, please contact Infrastructure at: [email protected] --------------------------------------------------------------------- To unsubscribe, e-mail: [email protected] For additional commands, e-mail: [email protected]

