GitHub user carloea2 added a comment to the discussion: Support Arrow batches
as an explicit Python UDF input and output mode
Added the diagram to the opening post: 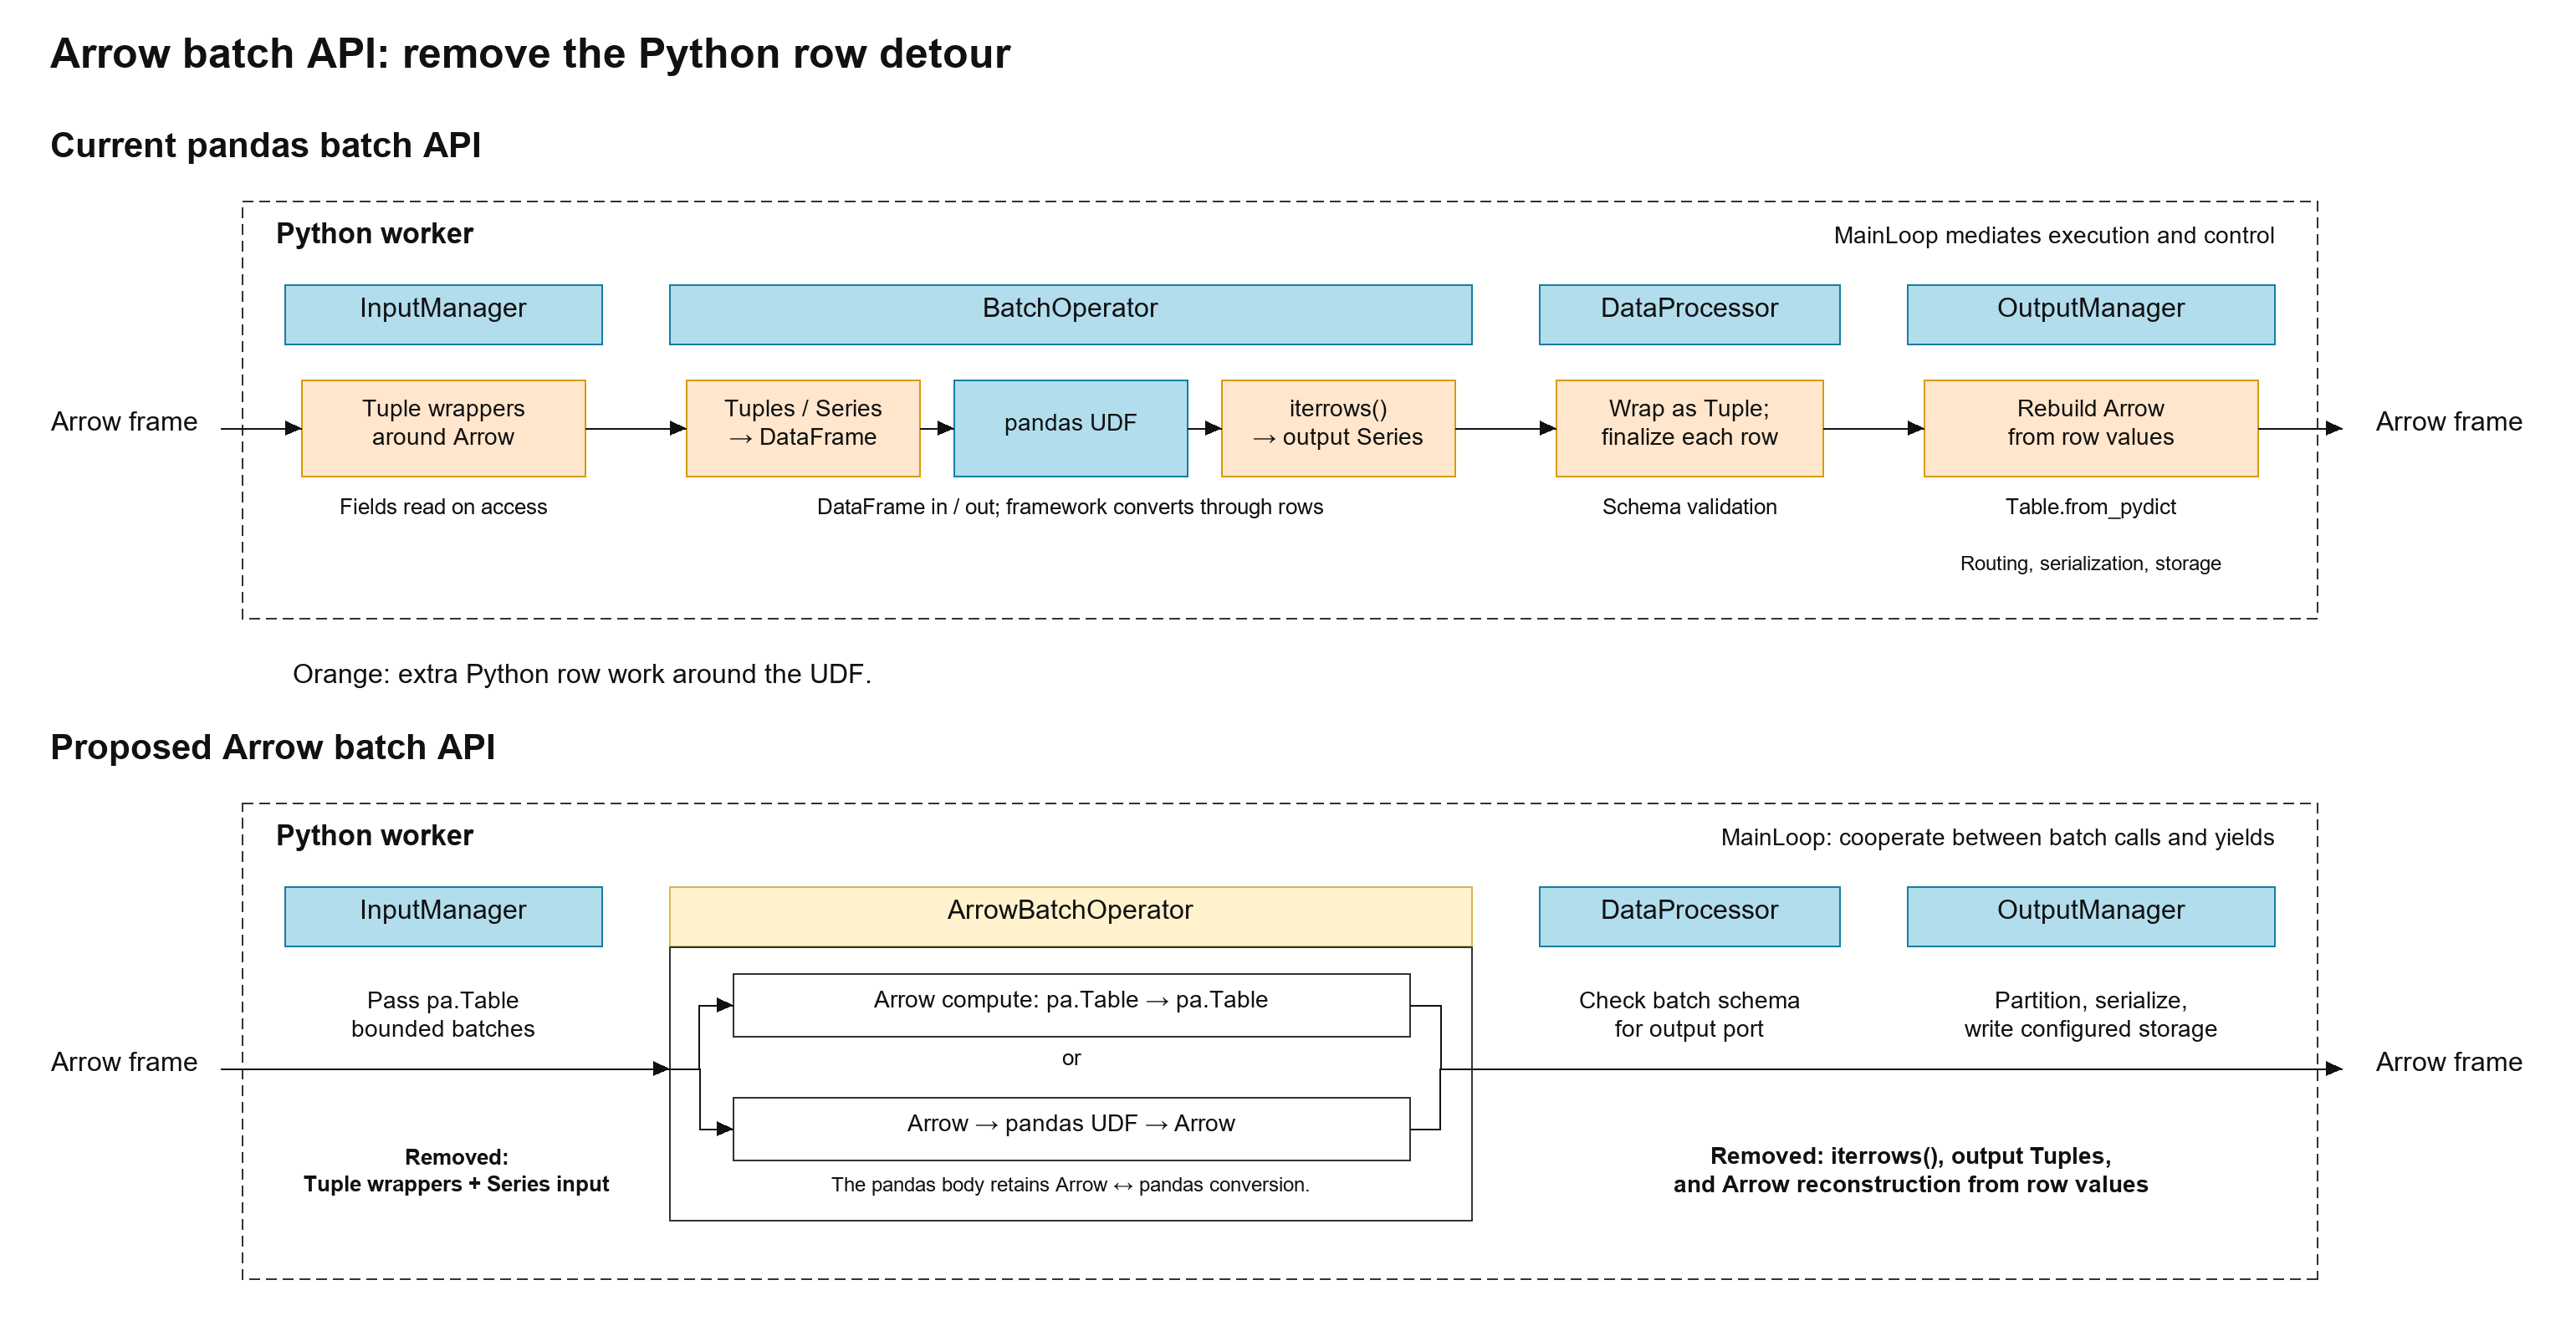 The orange steps show the framework row work being removed: Tuple/Series input construction, output `iterrows()`, output Tuples, and rebuilding Arrow from row values. The existing managers remain, along with schema checks, routing and storage responsibilities. The pandas-body option is shown separately because it still pays Arrow ↔ pandas conversion. I also added the new time/memory measurements and the [full benchmark evidence](https://github.com/carloea2/texera/blob/658529d733109d09371a01b3782d50c7eebafc3b/docs/benchmarks/arrow-batches-2026-11-04/benchmark/results.md). The lower path is still a proposal; the measured direct paths are standalone prototypes. GitHub link: https://github.com/apache/texera/discussions/8477#discussioncomment-19404256 ---- This is an automatically sent email for [email protected]. To unsubscribe, please send an email to: [email protected]

