bitflicker64 commented on issue #3227:
URL: https://github.com/apache/hugegraph/issues/3227#issuecomment-5795391573
Diagram of the mechanism, and answers to the two questions from review: how rare the trigger is, and whether the fix is contained. 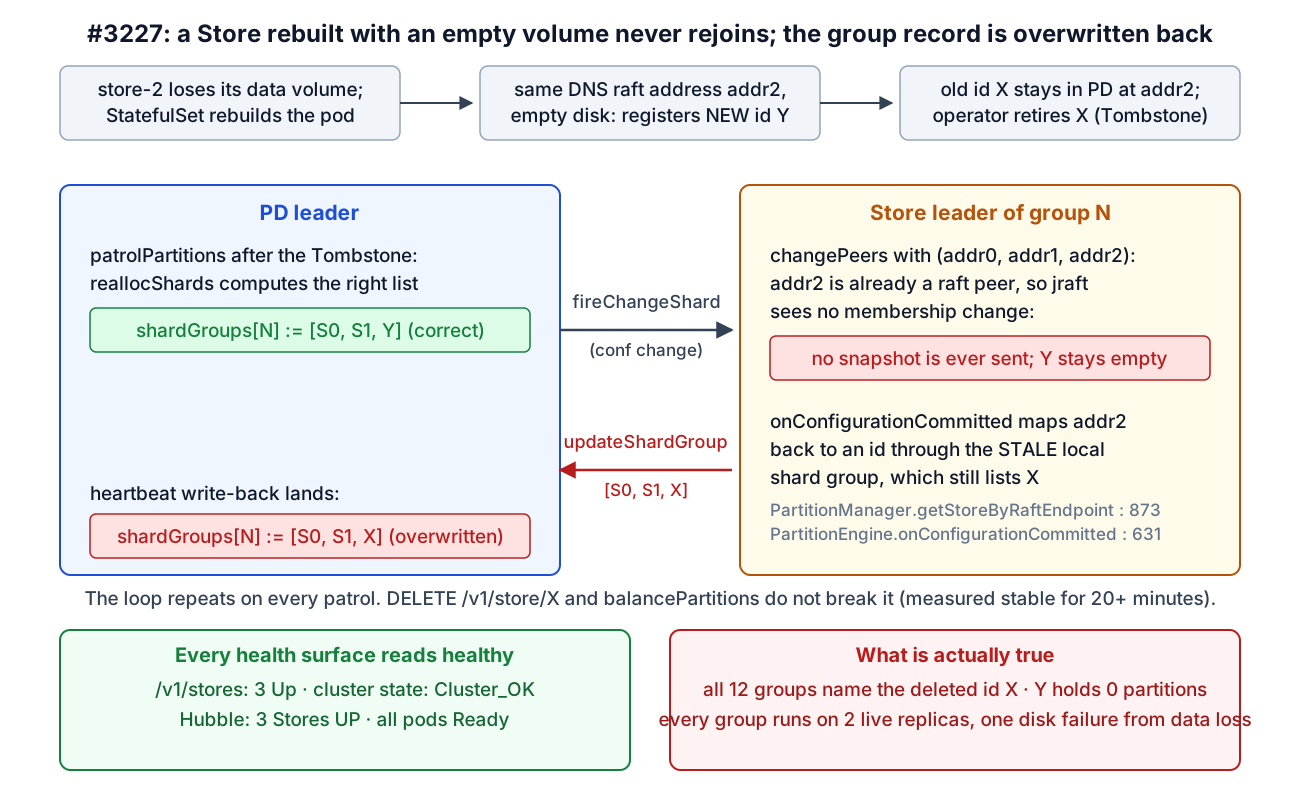 **Trigger.** The event is uncommon (a Store's data volume lost: disk failure, PVC deletion, node loss with local storage). The path is not: on Kubernetes a StatefulSet always rebuilds the pod at the same DNS raft address, so this is the default recovery route after any volume loss, and a bare-metal rebuild reusing host:port hits the same code. The multiplier is silence: nothing reports the lost replica, so the state persists until the next failure makes it two of three lost. **Fix shape.** Two bounded parts, no protocol change: 1. Stop the overwrite: `getStoreByRaftEndpoint` falls back to PD's store list (preferring `Up`) when the id its local group holds for that address is no longer an active store. Small, `hg-store-core` only, fixes the bookkeeping. 2. Make data flow: the group needs a real membership change so jraft installs a snapshot on the new id. Either PD drives remove-then-add when `reallocShards` swaps the id at an unchanged address, or the Store creates the missing partition engine when a conf notice names an address it serves with no engine. A few hundred lines in one module, depending on which layer owns it. Which layer do you prefer for part 2? I can build it and re-run the measured scenario from this report as the regression check. -- This is an automated message from the Apache Git Service. To respond to the message, please log on to GitHub and use the URL above to go to the specific comment. To unsubscribe, e-mail: [email protected] For queries about this service, please contact Infrastructure at: [email protected] --------------------------------------------------------------------- To unsubscribe, e-mail: [email protected] For additional commands, e-mail: [email protected]

