bitflicker64 commented on PR #3237:
URL: https://github.com/apache/hugegraph/pull/3237#issuecomment-5853518230
## Design update: push from the commit plus a Server-held lease, replacing the 10 s poll @imbajin Following your review (O(1) notification, not polling) and your design doc of 2026-09-26, I redid the design from scratch instead of tuning the poll. This comment is the proposed design and how it was reached. Nothing new is pushed to this branch yet; I would like your agreement on the design and on the questions at the end before implementing it here in stages. 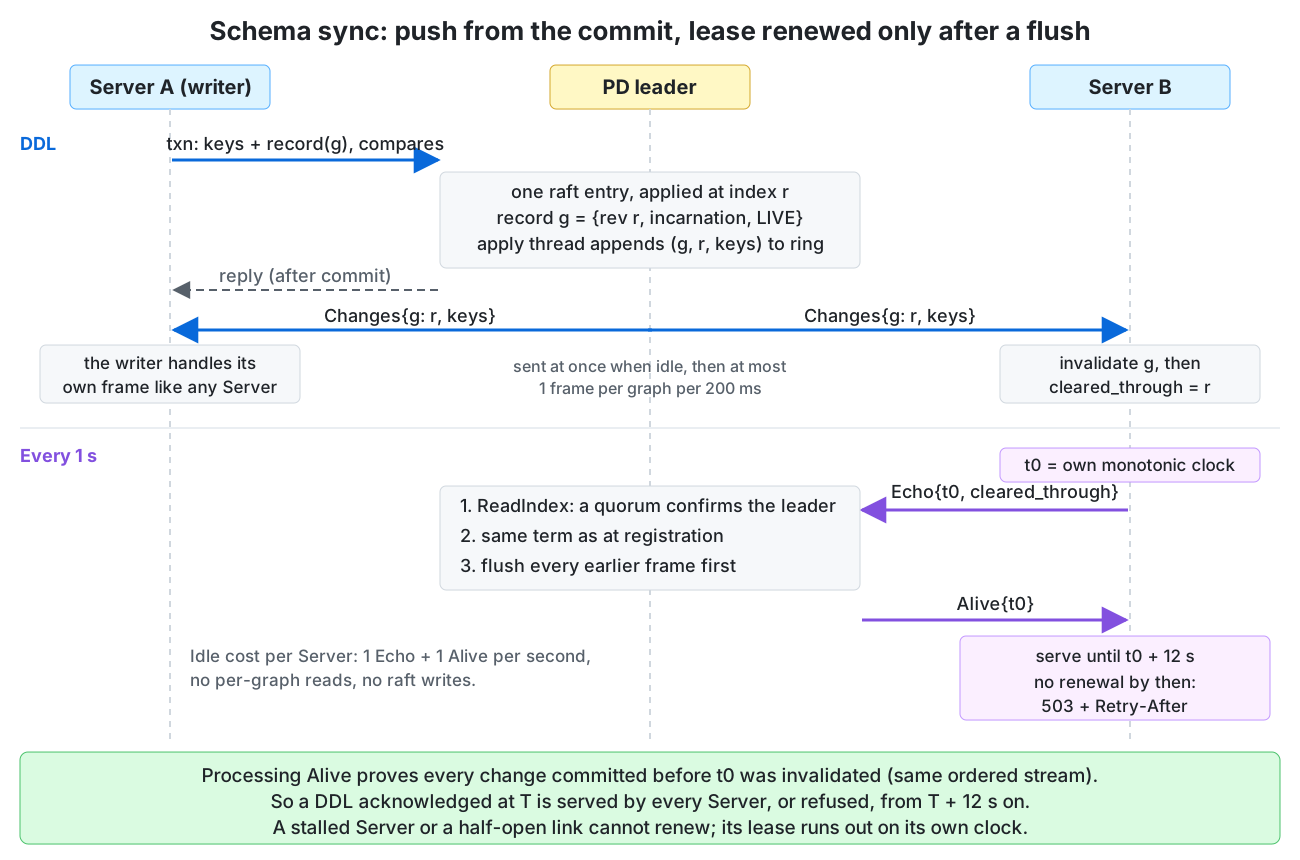 ### How the design was reached 1. **Verified the code first.** PD's KV write path, the KV watch, HgPdWatch and Pulse, the Server DDL paths, `LockUtil` and the schema caches. This turned up the master bugs listed below, which any design has to fix. 2. **Five independent designs** from different starting points: - your doc as written; - one aiming to beat it (every DDL waits for all Servers, as in Chubby); - one built on the existing KV watch; - one with a Server-held lease and no per-session state in PD; - one adapted from prior art: Chubby, etcd watch progress, Kubernetes informers, ZooKeeper, and F1 online schema change. Two more specs went deep on single layers: the PD commit layer and the Server cache. 3. **An adversarial review of each of the seven.** Every claim was re-checked against the code, and reviewers built failure interleavings. Every design had at least one flaw that lost a change or broke its bound. Each flaw had a local fix. 4. **One combined design** from the strongest mechanism of each, then three more review rounds on it: correctness under failure, cost and fit with your doc, and a final pass on what changed. 5. **A prototype of the protocol core** on 3 PD, 1 Store and 3 Servers, with fault injection. The numbers are below. ### The design 1. **Commit.** Each DDL step is one PD raft entry: a new `KvService.txn` carrying the element keys plus a per-graph record `{rev, incarnation, state}`. `rev` is the raft log index of that entry. The TXN compares each element's stored JSON with what the Server read (absent for a create) and the record's incarnation. So: - a DDL is all or nothing; - two Servers cannot silently overwrite each other; - a write for a dropped graph's old incarnation fails. A commit timeout resends the same request id; PD deduplicates inside apply and never re-proposes. Record states are CREATING, LIVE, DROPPING and DROPPED. 2. **Notify.** The apply thread appends each committed TXN to a bounded in-memory ring and never blocks. One sender on the leader merges per session and per graph, and sends the latest revision plus the keys that changed. - It sends at once when idle, then at most one frame per graph per 200 ms. - It sends only to Servers that have the graph open. - Frames go over one new bidi method, `KvService.sync`, on its own channel. The KV watch and the HgPdWatch subjects keep their current behaviour, so Store is not affected. 3. **ACK and lease.** Every second the Server sends an echo stamped with its own monotonic send time `t0` and the highest revision it has invalidated. PD answers with Alive only after three steps: 1. a ReadIndex (a quorum confirms it is still leader); 2. a check that its term is the one the session registered under; 3. a flush of every earlier frame on that stream. Processing that Alive proves the Server invalidated everything committed before `t0`, so it may serve until `t0 + 12 s`. Without a renewal by then, its gate answers 503 with `Retry-After`. The ACK is cumulative, per session, in memory, with no per-message retry. 4. **Handshake.** Hello registers the session with its open graphs, then comes a ReadIndex, then a snapshot of those graphs' records. The Server invalidates only graphs whose revision or incarnation moved, so a PD failover does not flush every cache. A graph opened later subscribes the same way and is registered before its first schema read. 5. **Server cache.** One immutable snapshot per graph, tagged with the revision it covers, replaces the id, name and array caches. A request pins one snapshot for its duration. A frame invalidates at once, then reads fetch only the changed keys at a proven revision; any gap falls back to a full load. The writer handles its own frame like every other Server (your 4.3). 6. **Rollout.** - PD goes first. The TXN op stays off until the leader has confirmed that every PD member supports it, because an old follower skips an unknown raft op. - A Server detects an old PD by `UNIMPLEMENTED` and keeps the current behaviour. - Servers roll with DDL frozen. **Staleness bound.** If a DDL is acknowledged at time T, then from T + 12 s every Server either serves it or answers 503 on that graph. The bound depends only on the Server's own clock rate. It holds under a Server stall, half-open TCP, a PD leader change including a partitioned old leader, and crashes. Requests already running keep the schema they started with. ### Measured Prototype of the PD TXN with the record, the ring and sender, `KvService.sync`, and the Server session, lease, gate and TXN writes. It was built on master `83ef9f3fa` and is not pushed yet. Run on 2026-09-27 on one 12-core host with 3 PD, 1 Store and 3 Servers on 127.0.0.1, Java 11. Server 0 made every DDL. | Test | Result | |---|---| | 200 sequential DDLs | PD apply to cache clear on the other Servers: p50 1 ms, p99 1 ms. Client ack to visible over REST: p50 8.2 ms, p99 16.8 ms (mostly the reload). | | 1,000 PK creates in 10 s | 50 to 51 frames and clears per Server, no 503 answers, all 1,000 listed on every Server. | | 10 min idle | 600 echoes and 600 Alives per Server; 0 frames, 0 KV reads, 0 KV writes from sync. | | PD leader `kill -9` | stream back in 2.4 s, 0 Servers fenced. Leader transfer: 0.39 s, 0 fenced. | | SIGSTOP a Server 30 s during DDL | 503 right after resume, fresh reads 80 ms later, 0 stale reads. | | Half-open link (a proxy that stops forwarding) | lease expired at the last good echo + 12.001 s; fresh 200 190 ms after the link returned. | | DDL during a handshake; graph opened mid-session | no change lost in either. | | Tests | PD core 112 of 112; unit 775; hstore core 816 on the second run (the first hit an `EdgeCoreTest` setup that races an async job against a 100 ms sleep). | One claim failed. A SIGSTOP of the first PD leader after cluster start leaves no new leader for about 11 s, and all 3 Servers fenced for 0.6 to 1.8 s. The cause is jraft's pre-vote, which blocks on the connect timeout while holding the node lock. PD sets that timeout from `raft.rpc-timeout` = 10 s (`RaftEngine.java:136`). Later leaders fail over in about 2 s. A separate 1 s connect timeout fixes it (Q7 below). Idle cost at 20 Servers is 72,000 small echo pairs per hour whatever the number of graphs, against 720,000 PD reads per hour for this PR's current poll with 100 open graphs. A DDL costs 1 raft entry instead of 4 to 10 puts today. ### Master bugs found on the way (fixed by this design) - **Lost updates across Servers.** `LockUtil` is JVM-local: - a same-name create on two Servers leaves two ID keys and one NAME key; - append and eliminate write JSON built from a possibly stale cache; - two IL creates on one base label can drop an IL id from `indexLabels`. - **Non-atomic DDL.** Every element write is an ID put then a NAME put, and multi-element DDLs span more puts. - **Cache races in `CachedSchemaTransactionV2`.** Local clears do not bump the generation, so a reader can re-install a deleted label. The `getAllSchema` hit path walks the cache without the lock and can return a truncated or empty list. - **Stale PD reads.** There is no ReadIndex, so a new leader can serve reads before applying earlier-term entries. - **The KV watch notifies outside apply.** It runs on the gRPC thread after the put, so changes applied by a new leader are never announced and order can invert. - **Drop/recreate race.** Drop deletes `GRAPH_CONF` before clearing schema, so a late clear can wipe a recreated graph. - **Truncate resets the id counter.** hstore truncate calls `resetIdByKey` (`HstoreSessionsImpl.java:806`) while the schema stays in PD, so new schema ids can collide with live ones. - **Store's schema cache only expires.** Store's `SchemaDriver` splits the clear event on `-` (`SchemaDriver.java:210`), but since #3011 the Server writes a JSON value. Updates never emit the event anyway, so the cache refreshes only when its entries expire. - **Builders mutate cached objects.** Schema builders change the cached object before the PD write succeeds, and `copy()` is shallow. ### Where it differs from your doc - **The Server fences when its lease ends, not at disconnect.** A half-open Server does not know it is disconnected, and fencing at disconnect would 503 every Server at every PD election. Measured: 0 fenced on kill, transfer and the later-leader SIGSTOP. - **No per-message ACK or retry timers.** One HTTP/2 stream delivers in order or fails, and a failed stream resyncs from the durable records. A per-message ACK adds no bound over the cumulative one. - **The revision is the raft log index.** It is monotonic per graph but not dense, and replay after a snapshot is safe with a skip rule. - **Transport.** It is a new method on an existing service rather than the existing watch path, so the watch behaviour Store shares stays unchanged. - **An immutable per-graph snapshot** replaces fine-grained caches under a generation. - **Changed keys in the frame.** This is not the object-level delta sync your section 1 excludes. It keeps no history, replays nothing and ships no values; the Server still invalidates first and reads authoritative values, and falls back to a full load on any gap. Without it, a 1,000-element schema script at 20 Servers moves the storm from clears to full reloads. - **The echo replaces transport keepalive.** PD's gRPC server keeps the library default policy, which rejects client keepalive pings more often than every 5 minutes, and no PD client sets keepalive, so there is none to reuse. - **Barrier DDL is proposed separately** (next section). ### Not in this PR: barrier DDL A wait-for-all-Servers step before index rebuild and label or index removal is designed, but it failed every review round. The last gap is a Store write that the client gave up on but Store still applies after the barrier; only Store-side fencing closes that. Cross-Server rebuild and removal are also unsafe on master today, independent of the cache. So it is a separate proposal, as your TODO 2 frames it. In this PR those DDLs still commit atomically and reach every Server within the 12 s bound, and a Server that has seen DELETING rejects new writes to that label. ### Stages on this branch - **A.** Master bug fixes that stand alone: the truncate id reset, ReadIndex in `IdMetaStore.getId`, and a synchronous snapshot checkpoint. - **B.** Copy-on-write at the schema mutation sites. - **C.** The PD TXN and record, dormant behind the flag. - **D.** Server DDL through the TXN, with compares and migration of existing graphs. - **E.** Sync as one unit: stream, handshake, lease, gate and snapshot cache. The poll, the version key and the event puts are removed. No stage ships sessions without the lease and the resync that recover them. ### Questions 1. Host `sync` on `KvService` next to `txn` (my recommendation) or as a new method on `HgPdWatch`? 2. Defaults: echo every 1 s, lease 12 s, coalescing window 200 ms. Fence at lease end only, as proposed? 3. Store's schema cache: fix the event parse and have Store watch the record keys in this PR, or in a follow-up? 4. Store-side fencing and the barrier proposal: take them as a follow-up design, and in which order? 5. Make `GRAPH_CONF` and the schema prefixes TXN-only once the flag is on (plain puts refused)? 6. Keep schema on hstore truncate? The id reset is removed either way. 7. Give PD a separate raft connect timeout (1 s) so the first-leader failover takes about 2 s instead of 11 s? The full specification is about 20,000 words; I will put the parts you want into the PR body and the doc PR (apache/hugegraph-doc#498) once the design is agreed. The blocking point in your inline comment (a writer crash between the schema write and the version write) goes away with the atomic TXN; I will answer it there. -- This is an automated message from the Apache Git Service. To respond to the message, please log on to GitHub and use the URL above to go to the specific comment. To unsubscribe, e-mail: [email protected] For queries about this service, please contact Infrastructure at: [email protected] --------------------------------------------------------------------- To unsubscribe, e-mail: [email protected] For additional commands, e-mail: [email protected]

